|
|
|
| Multi-view decoupled fusion for multimodal emotion recognition in conversation |
Tingting ZHANG( ),Xiaofei ZHU*() |
| College of Computer Science and Engineering, Chongqing University of Technology, Chongqing 400054, China |
|
|
|
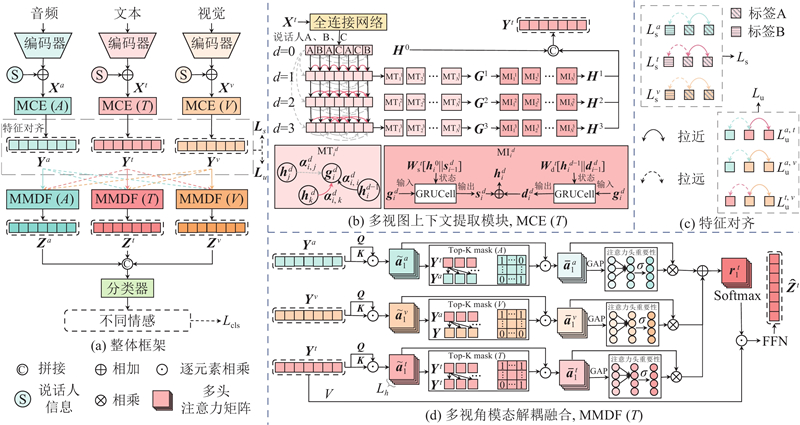
Abstract A multi-view decoupled fusion (MDF) framework was proposed to address the limitations of existing methods for multimodal emotion recognition in conversation (MERC) regarding context modeling and multimodal fusion. A multi-view context extraction module was designed to capture emotional dependencies in conversation through multi-scale contextual views from near to far. Furthermore, the discriminative ability was enhanced by combining supervised and unsupervised learning strategies. In addition, a multi-view modal decoupled fusion module was introduced, in which a Top-K mask mechanism was utilized to filter noise in attention matrices, and the expressive capability was improved by modeling the importance of each attention head. Experimental results on mainstream datasets demonstrated that, compared with the state-of-the-art method AdaIGN, the MDF achieved significant improvements in both context extraction and multimodal fusion. Specifically, on the IEMOCAP dataset, the accuracy (Acc) and weighted F1-score (W-F1) were improved by 2.38 and 2.31 percentage points, respectively; on the MELD dataset, Acc and W-F1 were improved by 0.44 and 0.13 percentage points, respectively. These results validated the effectiveness of the MDF framework.
|
|
Received: 30 August 2025
Published: 16 October 2026
|
|
|
| Fund: 国家自然科学基金资助项目(62472059);重庆英才计划项目(CSTC2024YCJH-BGZXM0022);重庆市技术创新与应用发展专项重大项目(CSTB2024TIAD-STX0027). |
|
Corresponding Authors:
Xiaofei ZHU
E-mail: ztt@stu.cqut.edu.cn;zxf@cqut.edu.cn
|
基于多视角解耦融合的多模态会话情感识别
现有多模态会话情感识别(MERC)方法在上下文建模和多模态融合方面存在局限,为此提出多视角解耦融合(MDF)框架. 设计多视图上下文提取模块,通过构建从近到远的多尺度语境视图,全面捕捉会话中的情感依赖. 结合有监督与无监督学习策略,增强模型的判别能力. 引入多视角模态解耦融合模块,采用Top-K掩码机制有效过滤注意力矩阵中的噪声,通过建模各注意力头的重要性,进一步提升模型表达能力. 在主流数据集上开展的模型性能对比实验结果表明,与先进方法AdaIGN相比,MDF 在上下文提取和模态融合方面优势显著:在IEMOCAP数据集上,MDF的准确率 (Acc) 和加权F1值 (W-F1) 分别提升了2.38和2.31个百分点; 在MELD数据集上,Acc和W-F1分别提升了0.44和0.13个百分点. 实验结果验证了MDF框架的有效性.
关键词:
情感识别,
多模态学习,
多视图上下文提取,
多视角解耦融合,
对比学习
|
|
| [1] |
JOSHI A, BHAT A, JAIN A, et al. COGMEN: contextualized GNN based multimodal emotion recognition [C]// Proceedings of the 2022 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies. Seattle: Association for Computational Linguistics, 2022: 4148–4164.
|
|
|
| [2] |
ZHENG X, ZHAO G, ZHU L, et al. PERD: personalized emoji recommendation with dynamic user preference [C]// Proceedings of the 45th International ACM SIGIR Conference on Research and Development in Information Retrieval. Madrid: ACM, 2022: 1922–1926.
|
|
|
| [3] |
PHANEENDRA BOTTU V S G S, RAGAVAN K Emotion-based music recommendation system integrating facial expression recognition and lyrics sentiment analysis[J]. IEEE Access, 2025, 13: 87740- 87752
doi: 10.1109/ACCESS.2025.3570011
|
|
|
| [4] |
FOTOPOULOU E, CASSÀ È L, MAVRAIDI L, et al EduCardia: a modern technology-powered methodology for the assessment and improvement of social and emotional competencies of students in K12 schools[J]. IEEE Access, 2025, 13: 10786- 10804
doi: 10.1109/ACCESS.2025.3529120
|
|
|
| [5] |
KHAN N D, ALI KHAN J, LI J, et al Leveraging large language model ChatGPT for enhanced understanding of end-user emotions in social media feedbacks[J]. Expert Systems with Applications, 2025, 261: 125524
doi: 10.1016/j.eswa.2024.125524
|
|
|
| [6] |
GIACOMUZZO G, TERRERAN M, JAIN S, et al. DECAF: a discrete-event based collaborative human-robot framework for furniture assembly [C]// Proceedings of the IEEE/RSJ International Conference on Intelligent Robots and Systems. Abu Dhabi: IEEE, 2024: 7085–7091.
|
|
|
| [7] |
YE J, WEI Y, WEN X C, et al. Emo-DNA: emotion decoupling and alignment learning for cross-corpus speech emotion recognition [C]// Proceedings of the 31st ACM International Conference on Multimedia. Ottawa: ACM, 2023: 5956–5965.
|
|
|
| [8] |
SHI T, HUANG S L. MultiEMO: an attention-based correlation-aware multimodal fusion framework for emotion recognition in conversations [C]// Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). Toronto: Association for Computational Linguistics, 2023: 14752–14766.
|
|
|
| [9] |
GHOSAL D, MAJUMDER N, PORIA S, et al. DialogueGCN: a graph convolutional neural network for emotion recognition in conversation [C]// Proceedings of the 2019 Conference on Empirical Methods in Natural Language Processing and the 9th International Joint Conference on Natural Language Processing (EMNLP-IJCNLP). Hong Kong: Association for Computational Linguistics, 2019: 154–164.
|
|
|
| [10] |
HU J, LIU Y, ZHAO J, et al. MMGCN: multimodal fusion via deep graph convolution network for emotion recognition in conversation [C]// Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers). [S.l.]: Association for Computational Linguistics, 2021: 5666–5675.
|
|
|
| [11] |
HU D, HOU X, WEI L, et al. MM-DFN: multimodal dynamic fusion network for emotion recognition in conversations [C]// Proceedings of the ICASSP 2022—2022 IEEE International Conference on Acoustics, Speech and Signal Processing. Singapore: IEEE, 2022: 7037–7041.
|
|
|
| [12] |
SHEN W, WU S, YANG Y, et al. Directed acyclic graph network for conversational emotion recognition [C]// Proceedings of the 59th Annual Meeting of the Association for Computational Linguistics and the 11th International Joint Conference on Natural Language Processing (Volume 1: Long Papers). [S.l.]: Association for Computational Linguistics, 2021: 1551–1560.
|
|
|
| [13] |
NGUYEN C T, NGUYEN C B, LE D T, et al. Curriculum learning meets directed acyclic graph for multimodal emotion recognition [C]// Proceedings of the 2024 Joint International Conference on Computational Linguistics, Language Resources and Evaluation (LREC-COLING 2024). Torino: Association for Computational Linguistics, 2024: 4259–4265.
|
|
|
| [14] |
BALTRUŠAITIS T, AHUJA C, MORENCY L P Multimodal machine learning: a survey and taxonomy[J]. IEEE Transactions on Pattern Analysis and Machine Intelligence, 2019, 41 (2): 423- 443
doi: 10.1109/TPAMI.2018.2798607
|
|
|
| [15] |
LI J, JI D, LI F, et al. HiTrans: a Transformer-based context- and speaker-sensitive model for emotion detection in conversations [C]// Proceedings of the 28th International Conference on Computational Linguistics. Barcelona: Association for Computational Linguistics, 2020: 4190–4200.
|
|
|
| [16] |
LIAN Z, LIU B, TAO J CTNet: conversational transformer network for emotion recognition[J]. IEEE/ACM Transactions on Audio, Speech, and Language Processing, 2021, 29: 985- 1000
doi: 10.1109/TASLP.2021.3049898
|
|
|
| [17] |
ZHANG X, LI Y. A cross-modality context fusion and semantic refinement network for emotion recognition in conversation [C]// Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 1: Long Papers). Toronto: Association for Computational Linguistics, 2023: 13099–13110.
|
|
|
| [18] |
MA H, WANG J, LIN H, et al A transformer-based model with self-distillation for multimodal emotion recognition in conversations[J]. IEEE Transactions on Multimedia, 2024, 26: 776- 788
doi: 10.1109/TMM.2023.3271019
|
|
|
| [19] |
YUN T, LIM H, LEE J, et al. TelME: teacher-leading multimodal fusion network for emotion recognition in conversation [C]// Proceedings of the 2024 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies (Volume 1: Long Papers). Mexico City: Association for Computational Linguistics, 2024: 82–95.
|
|
|
| [20] |
ISHIWATARI T, YASUDA Y, MIYAZAKI T, et al. Relation-aware graph attention networks with relational position encodings for emotion recognition in conversations [C]// Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing (EMNLP). [S.l.]: Association for Computational Linguistics, 2020: 7360–7370.
|
|
|
| [21] |
TU G, XIE T, LIANG B, et al Adaptive graph learning for multimodal conversational emotion detection[J]. Proceedings of the AAAI Conference on Artificial Intelligence, 2024, 38 (17): 19089- 19097
doi: 10.1609/aaai.v38i17.29876
|
|
|
| [22] |
LI M, SHI J, BAI L, et al FrameERC: framelet transform based multimodal graph neural networks for emotion recognition in conversation[J]. Pattern Recognition, 2025, 161: 111340
doi: 10.1016/j.patcog.2024.111340
|
|
|
| [23] |
LI Z, TANG F, ZHAO M, et al. EmoCaps: emotion capsule based model for conversational emotion recognition [C]// Proceedings of the Findings of the Association for Computational Linguistics. Dublin: Association for Computational Linguistics, 2022: 1610–1618.
|
|
|
| [24] |
YANG H, GAO X, WU J, et al. Self-adaptive context and modal-interaction modeling for multimodal emotion recognition [C]// Proceedings of the Findings of the Association for Computational Linguistics. Toronto: Association for Computational Linguistics, 2023: 6267–6281.
|
|
|
| [25] |
SCHULLER B, BATLINER A, STEIDL S, et al Recognising realistic emotions and affect in speech: state of the art and lessons learnt from the first challenge[J]. Speech Communication, 2011, 53 (9/10): 1062- 1087
doi: 10.1016/j.specom.2011.01.011
|
|
|
| [26] |
LIU Y, OTT M, GOYAL N, et al. RoBERTa: a robustly optimized BERT pretraining approach [EB/OL]. (2019–07–26)[2025–10–22]. https://arxiv.org/pdf/1907.11692.
|
|
|
| [27] |
HUANG G, LIU Z, VAN DER MAATEN L, et al. Densely connected convolutional networks [C]// Proceedings of the IEEE Conference on Computer Vision and Pattern Recognition. Honolulu: IEEE, 2017: 2261–2269.
|
|
|
| [28] |
XIE Y, ZHOU P, KIM S. Decoupled side information fusion for sequential recommendation [C]// Proceedings of the 45th International ACM SIGIR Conference on Research and Development in Information Retrieval. Madrid: ACM, 2022: 1611–1621.
|
|
|
| [29] |
BUSSO C, BULUT M, LEE C C, et al IEMOCAP: interactive emotional dyadic motion capture database[J]. Language Resources and Evaluation, 2008, 42 (4): 335- 359
doi: 10.1007/s10579-008-9076-6
|
|
|
| [30] |
PORIA S, HAZARIKA D, MAJUMDER N, et al. MELD: a multimodal multi-party dataset for emotion recognition in conversations [C]// Proceedings of the 57th Annual Meeting of the Association for Computational Linguistics. Florence: Association for Computational Linguistics, 2019: 527–536.
|
|
|
|
Viewed |
|
|
|
Full text
|
|
|
|
|
Abstract
|
|
|
|
|
Cited |
|
|
|
|
| |
Shared |
|
|
|
|
| |
Discussed |
|
|
|
|