|
|
|
| Dynamic Monte-Carlo reinforcement learning based on adversarial graph generation |
Li SONG1,2( ),Yuanyu WAN4,Canghong JIN3,*(),Mingli SONG2 |
1. College of Information Science and Technology, Zhejiang Shuren University, Hangzhou 310015, China
2. College of Computer Science and Technology, Zhejiang University, Hangzhou 310027, China
3. School of Computer and Computing Science, Hangzhou City University, Hangzhou 310015, China
4. School of Software Technology, Zhejiang University, Ningbo 315100, China |
|
|
|
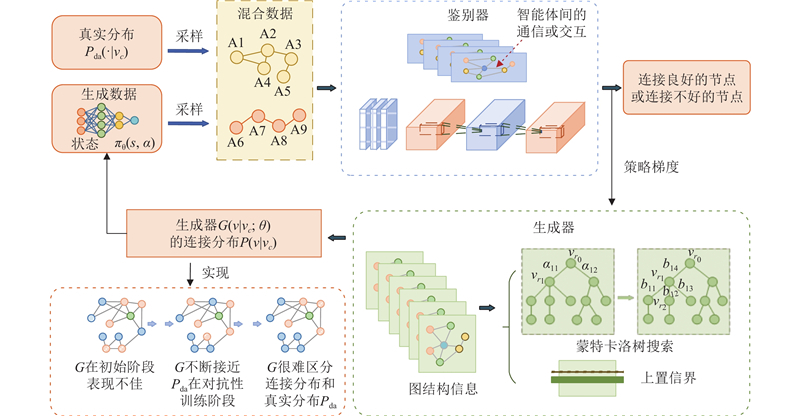
Abstract A multi-agent dynamic Monte-Carlo reinforcement learning based on adversarial graph generation (GGAN-MCRL) algorithm was proposed in order to address the issue that traditional graph reinforcement learning (GRL) cannot dynamically generate or adjust graph structure due to the assumption that the graph topology and node connections remain unchanged in a short period of time in scenarios where nodes or edges frequently change. Dynamic graphs were generated to model the relationships and interactions of agents. The key idea was to exploit a graph generative adversarial network (GGAN) to capture real-time changes of nodes or edges in dynamic graphs. Graph softmax was adopted in GGAN-MCRL compared with directly applying GGAN in GRL. Then the interaction strength between agents decreased with the increase of distance, thereby reducing redundant computation. An improved upper confidence bound mechanism was combined with GGAN-MCRL to enhance exploration capability and reduce ineffective searches. The experimental results show that GGAN-MCRL has better strategies and higher computational efficiency in dynamic and high-dimensional environments.
|
|
Received: 19 September 2025
Published: 21 October 2026
|
|
|
| Fund: 浙江省“尖兵领雁+X”科技计划资助项目(2025C04019, 2024C01072);浙江省自然科学基金联合基金资助项目(LHZSD24F020001);国家自然科学基金资助项目(62306275, U20B2066). |
|
Corresponding Authors:
Canghong JIN
E-mail: slili516@zjsru.edu.cn;jinch@hzcu.edu.cn
|
基于对抗图生成的动态蒙特卡洛强化学习
为了解决传统图强化学习(GRL)在节点或边频繁变化的实际场景中,因假设图拓扑与节点连接在短时间内保持不变而无法动态生成或调整图结构的问题,提出基于对抗图生成的多智能体动态蒙特卡洛强化学习算法(GGAN-MCRL),以生成动态图来模拟智能体之间的关系和互动. 该算法的关键思想是利用图生成对抗网络(GGAN)来捕捉动态图中节点或边的实时变化. 与直接在GRL中应用GGAN相比,GGAN-MCRL采用图softmax,使得智能体间的交互强度随距离的增加而衰减,削减了冗余计算. 结合改进的上置信界机制以增强探索能力,降低无效搜索. 实验结果表明,GGAN-MCRL在动态和高维环境中的策略更优,计算效率更高.
关键词:
多智能体强化学习,
图生成对抗网络,
改进的上置信界,
图softmax
|
|
| [1] |
李大字, 刘子博, 包琰洋, 等 图强化学习算法及其在工业领域的应用研究综述[J]. 国防科技大学学报, 2025, 47 (4): 76- 90
Li Dazi, Liu Zibo, Bao Yanyang, et al Research review of graph reinforcement learning algorithms and their applications in the industrial field[J]. Journal of National University of Defense Technology, 2025, 47 (4): 76- 90
doi: 10.11887/j.issn.1001-2486.24120028
|
|
|
| [2] |
李岳珩, 谢广明 集中训练分布执行下的多智能体强化学习综述[J]. 控制理论与应用, 2025, 42 (11): 2114- 2124
Li Yueheng, Xie Guangming Review of multi-agent reinforcement learning under centralized training with decentralized execution[J]. Control Theory and Applications, 2025, 42 (11): 2114- 2124
doi: 10.7641/CTA.2025.50009
|
|
|
| [3] |
Peng H, Shen X Multi-agent reinforcement learning based resource management in MEC- and UAV-assisted vehicular networks[J]. IEEE Journal on Selected Areas in Communications, 2021, 39 (1): 131- 141
doi: 10.1109/JSAC.2020.3036962
|
|
|
| [4] |
Yu T, Wang X, Hu J, et al Multi-agent proximal policy optimization-based dynamic client selection for federated AI in 6G-oriented Internet of vehicles[J]. IEEE Transactions on Vehicular Technology, 2021, 73 (9): 13611- 13624
doi: 10.1109/tvt.2024.3383860
|
|
|
| [5] |
Ding S, Du W, Ding L, et al Multiagent reinforcement learning with graphical mutual information maximization[J]. IEEE Transactions on Neural Networks and Learning Systems, 2025, 36 (11): 19515- 19524
doi: 10.1109/TNNLS.2023.3243557
|
|
|
| [6] |
Goeckner A, Sui Y Y, Martinet N, et al. Graph neural network-based reinforcement learning for multi-agent systems [C]// 36th Conference on Neural Information Processing Systems. New Orleans: MIT Press, 2022: 1–8.
|
|
|
| [7] |
Jiang J C, Dun C, Huang T J, et al. Graph convolutional reinforcement learning [C]// Proceedings of the 8th International Conference on Learning Representations. Addis Ababa: [s.n.], 2020: 1–13.
|
|
|
| [8] |
Wang S, Ji W, Gui H, et al XMIX: graph-based temporal credit assignment and attention-augmented value decomposition for multi-agent cooperative reinforcement learning[J]. Neurocomputing, 2025, 655: 131471
doi: 10.1016/j.neucom.2025.131471
|
|
|
| [9] |
Hu Y, Fu J, Wen G Graph soft actor–critic reinforcement learning for large-scale distributed multirobot coordination[J]. IEEE Transactions on Neural Networks and Learning Systems, 2025, 36 (1): 665- 676
doi: 10.1109/TNNLS.2023.3329530
|
|
|
| [10] |
Yang P F, Zheng T Y, Zhang S Y, et al Graph-meta-reinforcement-learning-based algorithm for task offloading in vehicular edge–cloud collaboration[J]. IEEE Transactions on Vehicular Technology, 2026, 75 (5): 8320- 8335
doi: 10.1109/TVT.2025.3626007
|
|
|
| [11] |
张名芳, 马健, 赵娜乐, 等 无信号交叉口处基于深度强化学习的智能网联车辆运动规划[J]. 浙江大学学报(工学版), 2024, 58 (9): 1923- 1934
Zhang Mingfang, Ma Jian, Zhao Nale, et al Intelligent connected vehicle motion planning at unsignalized intersections based on deep reinforcement learning[J]. Journal of Zhejiang University (Engineering Science), 2024, 58 (9): 1923- 1934
|
|
|
| [12] |
Fellek G, Farid A, Fujimura S, et al G-DGANet: gated deep graph attention network with reinforcement learning for solving traveling salesman problem[J]. Neurocomputing, 2024, 579: 127392
doi: 10.1016/j.neucom.2024.127392
|
|
|
| [13] |
Nie M, Chen D, Wang D Reinforcement learning on graphs: a survey[J]. IEEE Transactions on Emerging Topics in Computational Intelligence, 2023, 7 (4): 1065- 1082
doi: 10.1109/TETCI.2022.3222545
|
|
|
| [14] |
Xu S, Guo S Distributed reactive power optimization for energy Internet via multiagent deep reinforcement learning with graph attention networks[J]. IEEE Transactions on Industrial Informatics, 2024, 20 (6): 8696- 8706
doi: 10.1109/TII.2023.3342467
|
|
|
| [15] |
Wang Y, Shi D, Xue C, et al. AHAC: actor hierarchical attention critic for multi-agent reinforcement learning [C]//Proceedings of the IEEE International Conference on Systems, Man, and Cybernetics. Toronto: IEEE, 2020: 3013–3020.
|
|
|
| [16] |
Lim B, Vu M Distributed multi-agent deep Q-learning for load balancing user association in dense networks[J]. IEEE Wireless Communications Letters, 2023, 12 (7): 1120- 1124
doi: 10.1109/LWC.2023.3250492
|
|
|
| [17] |
Foerster J N, Assael Y M, Freitas N D, et al. Learning to communicate with deep multi-agent reinforcement learning [C]// 30th Conference on Neural Information Processing Systems. Changsha: MIT Press, 2016: 2145–2153.
|
|
|
| [18] |
Das A, Gervet T, Romoff J, et al. TarMAC: targeted multi-agent communication [C]//Proceedings of the International Conference on Machine Learning. Long Beach: ACM, 2019: 1538–1546.
|
|
|
| [19] |
Singh A, Jain T, Sukhbaatar S. Learning when to communicate at scale in multiagent cooperative and competitive tasks [C]//Proceedings of the 7th International Conference on Learning Representations, 2019: 1−16.
|
|
|
| [20] |
Liu C, Guan D, Yuan W, et al ITS2Graph: graph-based generative adversarial learning for imbalanced time series classification[J]. Neural Networks, 2025, 191: 107770
doi: 10.1016/j.neunet.2025.107770
|
|
|
| [21] |
Wang H, Dou Y, Chen C, et al. Attacking fake news detectors via manipulating news social engagement [C]//Proceedings of the ACM Web Conference. Austin: ACM, 2023: 3978–3986.
|
|
|
| [22] |
Wang L, Wang R, Jia G. Generative adversarial nets model based on spatio-temporal graph attention network for multi-step prediction [C]//Proceedings of the China Automation Congress. Chongqing: IEEE, 2024: 6954–6959.
|
|
|
| [23] |
Zhu J H, Wen G X, Veluvolu K C Optimized backstepping consensus control using adaptive observer-critic-actor reinforcement learning for strict-feedback multi-agent systems[J]. Journal of the Franklin Institute-Engineering and Applied Mathematics, 2024, 361 (6): 1- 23
doi: 10.1016/j.jfranklin.2024.106693
|
|
|
|
Viewed |
|
|
|
Full text
|
|
|
|
|
Abstract
|
|
|
|
|
Cited |
|
|
|
|
| |
Shared |
|
|
|
|
| |
Discussed |
|
|
|
|